TL;DR
- One platform, every team. n8n use cases span marketing, content, IT operations, and finance, each built as a trigger followed by a chain of nodes on the same platform.
- Reliability is built in. Credentials, Retry On Fail, and error workflows keep an unattended workflow from leaking keys or failing unnoticed.
- Browsers for no-API pages. When a workflow has to log in, render JavaScript, or save a page as a PDF, n8n calls Browserless from its HTTP Request node, and five worked workflows show how.
Introduction
n8n use cases start with the hours your team loses to re-keying leads into a customer relationship management (CRM) tool or downloading invoices from vendor portals. n8n links apps, APIs, databases, and artificial intelligence (AI) models into trigger-driven workflows that take that work over.
In this guide, you'll see where teams put n8n to work, from marketing to finance, then build five browser-based n8n workflows for the pages an API call can't reach.
What are n8n use cases?
n8n use cases are the repetitive tasks you'd otherwise handle with manual data entry across multiple systems, like copying a form submission into a CRM, watching a folder for new files, or summarizing a report with AI. You build each one as workflow automation on a visual canvas, where a trigger such as a schedule or webhook kicks off a chain of nodes that filter and reshape the data.
n8n works best when you're connecting tools that don't already talk to each other, especially when the logic in between needs an if/else or two. You can click any node and see exactly what went in and what came out, which makes custom workflows far easier to debug than a script on a server somewhere.
If you're building more than a handful of integrations, n8n is worth learning. Whoever inherits your workflow can read it off the canvas. The n8n repository has 200,000+ GitHub stars and lists 1,500+ integrations in its README, so there's a good chance a prebuilt node already exists for the tool you need.
Strictly speaking, n8n isn't open source software, since it ships as fair-code under the Sustainable Use License. The source is still public and you can run it self-hosted, which is what counts when data sovereignty rules out sending workflow data to someone else's cloud.
n8n use cases by category
Here are the workflows teams build in n8n most often, with common examples for each. Skim the categories that match your team, or jump straight to the n8n and Browserless section if your workflow has to work inside a real webpage.
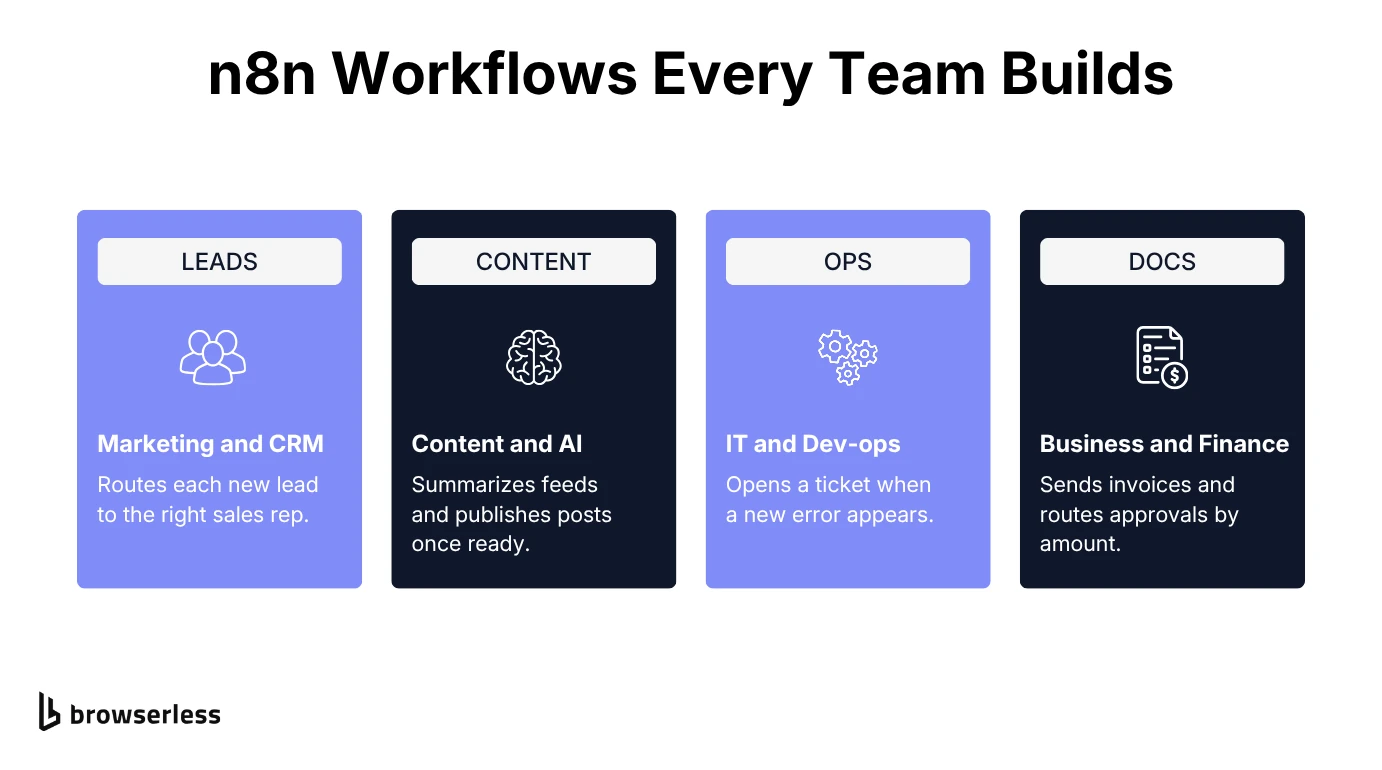
Marketing and CRM automation workflows
Marketing teams usually reach for n8n once a campaign spans more marketing tools than any one platform connects natively. It's also where marketing automation starts feeding the sales pipeline, with each qualified lead reaching the right rep the moment it comes in.
- Lead capture to CRM. Pull new leads from a web form or ad platform, enrich the lead data with a provider, run the CRM sync, and route each record to the right sales representative.
- Welcome email sequences. Send a welcome email the moment someone submits a form, with no manual export to your email tool.
- Cross-channel reporting. Pull weekly numbers from ad accounts and analytics tools into Google Sheets and post the summary to a Slack channel.
- Lead qualification. When a lead generation tool or a LinkedIn outreach campaign surfaces new contacts, score each one against your ideal customer profile so sales teams only see qualified leads in the CRM.
Content creation and AI automation workflows
For content teams, n8n takes over the manual tasks that sit between content creation and hitting publish.
- CMS publishing. Publish a post once it's marked ready in a tool like Notion or Airtable, with no copy-pasting into your CMS.
- AI summaries. Pull articles from an RSS feed, summarize them with an AI model, and send the summary to Slack or a social scheduler.
- Meeting notes. Turn a call transcript into meeting notes with action items and file them in Google Drive.
n8n's AI Agent node goes further by handing AI models a set of tools and letting them pick the next one based on the data. Use case 3 shows a simpler version, where the agent reviews a page Browserless has already rendered.
IT and dev-ops automation workflows
Engineering and ops teams lean on n8n for the small, repetitive jobs nobody wants to build and maintain a whole service for.
- Deployment notifications. Post to Slack when a pull request merges, then start the deployment step in the same workflow.
- Incident tickets. Watch an error tracker, and when a new issue appears, the workflow automatically opens a new ticket and alerts the on-call channel.
- Scheduled backups. Push a database dump to cloud storage, such as Google Drive or S3, on a scheduled trigger, with no cron job to maintain by hand.
When internal systems have no prebuilt node, drop into a Code node, where custom functions can call their APIs directly and hold logic like which alerts are worth paging someone at 2 a.m.
Business and finance automation workflows
Business and finance workflows tend to revolve around documents, for small businesses automating bookkeeping and enterprise teams with strict approval workflows alike. Each document is easy to handle on its own and miserable at volume.
- Invoice processing. Generate and send a PDF invoice after a payment clears, then write the record into your accounting software.
- Approval routing. Send each request to the right approver by amount or department, remind them when it stalls, and keep audit trails of who approved what.
- Timesheet rollups. Aggregate weekly hours from a timesheet tool, flag due dates, and email the result to managers.
n8n + Browserless: browser automation and scraping use cases
Everything above works because a built-in node can make API calls or receive a webhook. It falls apart the moment a task needs a real browser, like logging into a dashboard with no API, waiting for a JavaScript chart to render, or capturing a page the way a visitor sees it. The HTTP Request node only fetches the raw response, so it never runs the page's JavaScript or clicks through a login form.
What is Browserless? Browserless provides managed headless browsers in the cloud. You send it a URL or a script through its REST APIs or BrowserQL, its GraphQL-based query language, and it returns extracted data, a screenshot, a PDF, or rendered HTML.
You call Browserless from that same HTTP Request node, with your API token saved as an n8n credential and sent as the token query parameter, as the Browserless n8n docs lay out. Pick the regional endpoint closest to you, such as production-sfo or production-lon, and there's no browser library to install. The earlier guide to Browserless and n8n covers wiring the two together.
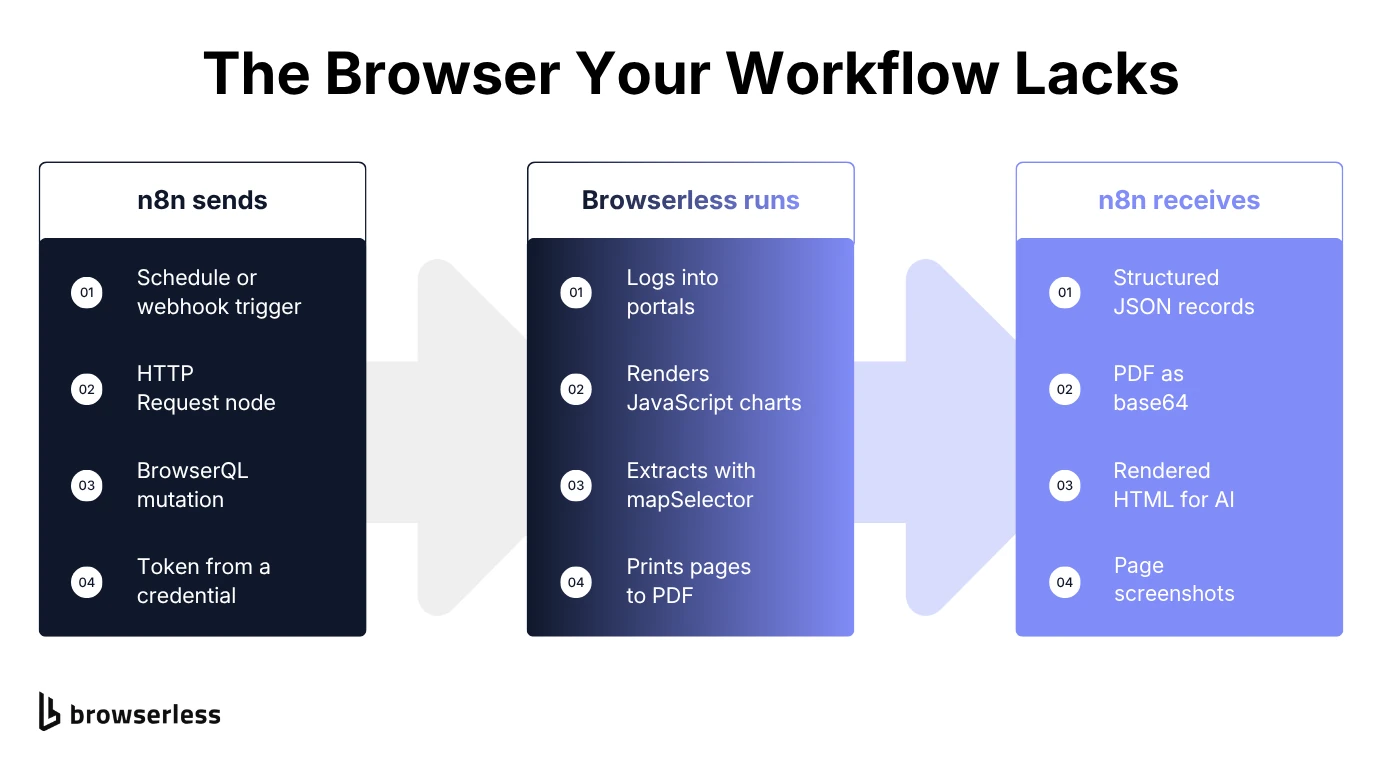
The five workflows below cover authenticated scraping, JavaScript-rendered PDF generation, AI-driven page analysis, e-commerce price and stock monitoring, and document capture from a gated vendor portal.
Use case 1: authenticated data extraction and CRM sync
Say you need data from a login-protected site, like a telecom dashboard or a supplier portal. Checking it by hand is error-prone and doesn't scale, so this workflow logs in, extracts the records you care about, and only triggers downstream logic when something relevant turns up.
To keep it runnable, the example logs into quotes.toscrape.com, a public practice site with a real login form, and pulls each quote with its author and tags. Only quotes by one author, Albert Einstein here, make it to the action step.
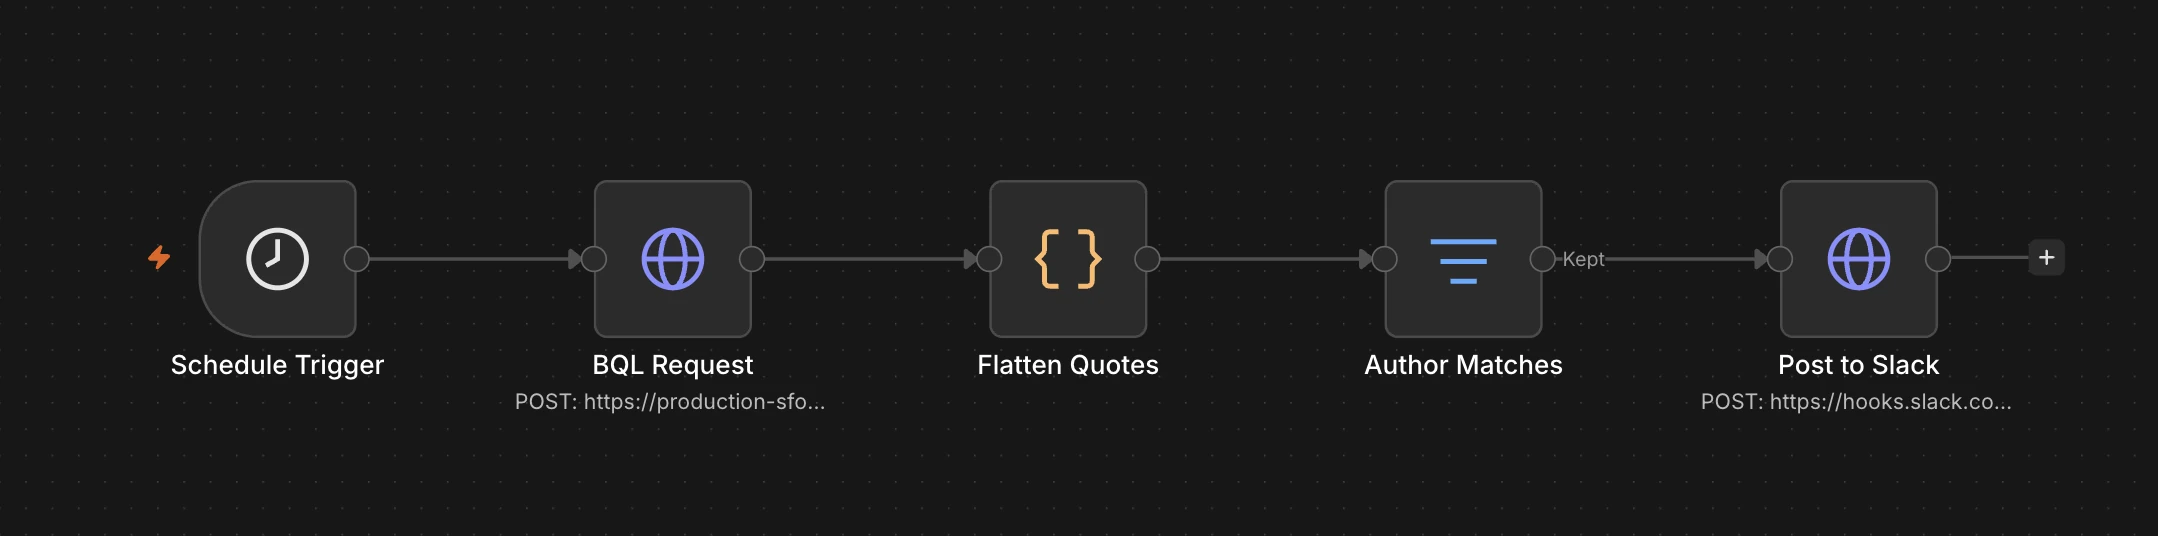
How the authenticated scraping workflow runs in n8n
Trigger. A Schedule Trigger node runs the workflow hourly or daily, depending on how often the content changes.
HTTP Request node (Browserless /chromium/bql). The node posts a BrowserQL mutation that fills in the login form, submits it, waits for the Logout link to appear, and loads the quotes page. mapSelector then turns each .quote element into an object holding its text, author, and tags. The full mutation goes in the node's JSON body as the query value.
mutation QuotesLoginScraper {
  reject(type: [image, media, font, stylesheet]) {
    enabled
    time
  }
  goto(url: "https://quotes.toscrape.com/login") {
    status
  }
  typeUsername: type(selector: "input[name='username']", text: "admin") {
    time
  }
  typePassword: type(selector: "input[name='password']", text: "admin") {
    time
  }
  clickSubmit: click(selector: "input[type='submit']") {
    time
  }
  waitPostLogin: waitForSelector(selector: "a[href='/logout']") {
    time
  }
  gotoQuotesPage: goto(url: "https://quotes.toscrape.com/") {
    status
  }
  quotes: mapSelector(selector: ".quote") {
    text: mapSelector(selector: ".text") {
      value: innerText
    }
    author: mapSelector(selector: ".author") {
      name: innerText
    }
    tags: mapSelector(selector: ".tags .tag") {
      tag: innerText
    }
  }
}
The response lists every quote on the page under data.quotes. mapSelector can match more than one element per card, so each field arrives wrapped in its own array. If your real portal shows a Cloudflare check or a CAPTCHA first, add a solve step after goto.
Logging in fresh on every run keeps the workflow stateless. For queries that run back to back, BrowserQL's reconnect mutation keeps the browser open (30 seconds by default) so the next query reuses its cookies and logged-in state. For gaps of hours between runs, a persisted session holds that state for the lifetime you set.
Code node. Those nested arrays are awkward to filter on, so a Code node unwraps them and returns each quote as its own n8n item.
const rawQuotes = $input.first().json.data?.quotes || [];
return rawQuotes.map((q) => ({
  json: {
    text: q.text?.[0]?.value || "",
    author: q.author?.[0]?.name || "",
    tags: (q.tags || []).map((t) => t.tag).filter(Boolean),
  },
}));
Now each item is a flat record, such as author: "Albert Einstein" with tags: ["change", "deep-thoughts", "thinking", "world"]. n8n's Filter node works item by item, so the split matters. Return one item holding an array and the filter has nothing to test.
Filter node. A Filter node keeps the items whose author matches and stops the run when none do, so downstream systems only hear about relevant records.
Action node. Matching records go to CRM systems such as HubSpot or Salesforce, where the matching n8n node creates or updates each one, or to Slack, email, or a webhook.
Where else authenticated scraping fits
Swap the quotes for stock-keeping units (SKUs) or support tickets, and the same workflow watches a partner dashboard or an authenticated ticketing system for the records your team cares about.
Use case 2: generate PDFs from JavaScript-rendered dashboards
Client reports usually mean a script glued to a PDF tool, or someone exporting by hand. Dashboards make it worse when they draw their charts client-side with libraries like Highcharts or D3 and offer no export. A plain HTTP request to those pages gets an empty chart container.
Here, the workflow loads the page in a real browser, lets the charts render, and saves the result as a PDF. The example uses the Bank of Canada's interest rates page, which draws its rate charts in the browser with amCharts.
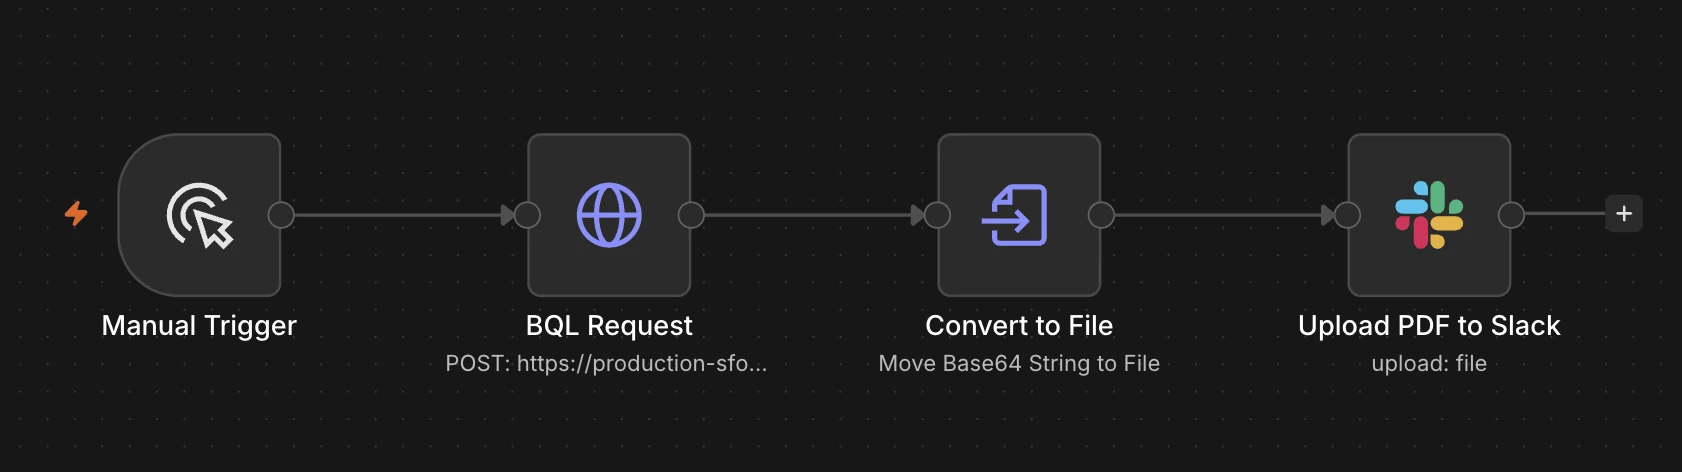
How the PDF report workflow runs in n8n
Trigger. A Manual Trigger starts the test run, and in production a Schedule Trigger can run it hourly, daily, or after an upstream data update.
HTTP Request node (Browserless /chromium/bql). The node sends a BrowserQL mutation that loads the page, waits for network activity to settle so the charts finish drawing, and prints it with the pdf mutation. You can try the same request from a terminal first with curl.
# Set BROWSERLESS_TOKEN to your API token before running
curl --request POST \
  --url "https://production-sfo.browserless.io/chromium/bql?token=$BROWSERLESS_TOKEN" \
  --header 'Content-Type: application/json' \
  --data @- <<'EOF'
{
  "query": "mutation PDFReport { goto(url: \"https://www.bankofcanada.ca/rates/interest-rates/\", waitUntil: networkIdle) { status } report: pdf(format: a4, printBackground: true, displayHeaderFooter: true, headerTemplate: \"<div style='font-size:10px;width:100%;text-align:center'>Interest Rates</div>\", footerTemplate: \"<div style='font-size:10px;width:100%;text-align:center'>Page <span class='pageNumber'></span> of <span class='totalPages'></span></div>\", marginTop: \"60px\", marginBottom: \"60px\") { base64 } }",
  "operationName": "PDFReport"
}
EOF
A successful run returns a status of 200 from goto and the PDF as a base64 string in data.report.base64. The header and footer take styled HTML, since Chrome prints plain text there at a near-invisible size, and the pageNumber and totalPages classes fill in the page count. Once it works from your terminal, paste the same JSON into the node's body.
Convert to File. n8n's Convert to File node turns the base64 string into a binary file that other nodes can send. If you call the REST /pdf endpoint instead, turn on the HTTP Request node's Download option and n8n receives the file as binary, so you can skip this step.
Slack or another output node. The PDF goes to the finance team's Slack channel. You could also upload it to storage, attach it to an email, or archive it with metadata in a database.
Where else PDF reports fit
Scheduled reports from analytics or finance dashboards are the obvious fit, along with compliance snapshots and any React-rendered summary that has no export. Add date-stamped filenames and you get a versioned archive for free.
Use case 3: LLM-powered SEO analysis of live pages
Checking every article by hand for meta tags, heading structure, alt text, and link quality works fine until you're publishing weekly, and then it quietly stops happening. Here, Browserless renders a live page and n8n hands the full HTML to a large language model (LLM) like Claude for a search engine optimization (SEO) review. Rendering matters because the model sees the page as a browser builds it, including markup that JavaScript adds after load.
How the LLM page review workflow runs in n8n
Trigger. A Manual Trigger keeps the example simple, though a schedule or a deployment webhook works the same way.
HTTP Request node (Browserless /chromium/bql). The node loads the page and returns its rendered HTML with the html mutation.
mutation SeoAudit {
  goto(
    url: "https://www.browserless.io/blog/browserless-n8n-ai-automation-workflows"
    waitUntil: networkIdle
  ) {
    status
  }
  html {
    html
  }
}
The response holds the page's full rendered markup in data.html.html, which is the value the AI step reads. Skip the clean option's removeNonTextNodes setting here. It shrinks the payload, but it also strips the <title>, <meta>, and <img> tags this audit needs. Unstripped, the example page comes back at about 335,000 characters, so pick a model whose context window can take a full page.
AI Agent node (Claude or OpenAI). The HTML goes to the model inside a structured SEO prompt, such as this one.
You are an SEO strategist reviewing an SEO article.
Based on the following HTML of the page content, assess:
- Whether the title and headings include relevant keywords for SEO
- If images are appropriately labeled with alt text
- Whether the internal and external links are descriptive and appropriate
- If the heading hierarchy (h1, h2, h3) is logical and consistent
Provide suggestions to improve SEO, structure, and accessibility.
OUTPUT: Provide a bullet-pointed summary with specific page improvement recommendations.
Here is the HTML: {{ $json.data.html.html }}
The {{ $json.data.html.html }} expression pulls the markup from the HTTP Request node into the prompt, so each run reviews whichever page that node just rendered.
Output node. The feedback posts to Slack or lands in a doc for the content team to act on.
Where else LLM page reviews fit
Point the same workflow at a blog archive or at every new post as a post-publish check, and swap the prompt per content type. Since the HTML comes from the rendered page, the review covers the live version, which can differ from what's stored in your CMS.
Use case 4: monitor e-commerce prices and stock in Google Sheets
Tracking competitor prices or your own storefront's inventory usually means someone refreshing product pages every morning, which falls apart past a handful of SKUs. Here, the workflow renders the listing, pulls each price and stock status out of the page, and only acts when something changes.
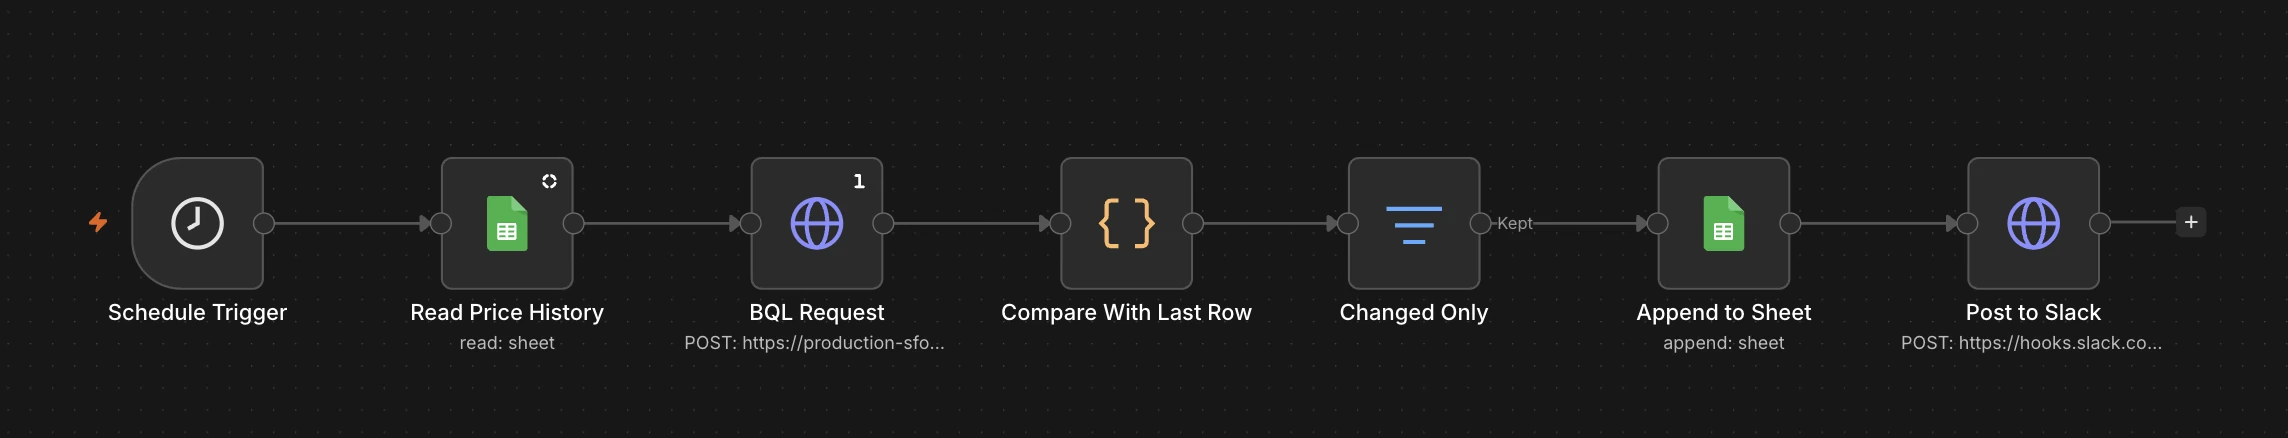
How the price monitoring workflow runs in n8n
Trigger. A Schedule Trigger runs the check hourly for fast-moving categories or daily for slower ones.
Google Sheets node. A Google Sheets node reads the rows recorded on earlier runs. It hands the next node one item per row, so turn on Execute Once in the HTTP Request node's settings, or Browserless loads the same listing once per row.
HTTP Request node (Browserless /chromium/bql). Browserless loads the listing and maps each product card into a title, price, and stock status with mapSelector, the same pattern as use case 1. The visible link text is truncated on this site, so the title comes from the link's title attribute.
mutation PriceStockMonitor {
  reject(type: [image, font, stylesheet]) {
    enabled
  }
  goto(url: "https://books.toscrape.com/") {
    status
  }
  products: mapSelector(selector: ".product_pod") {
    title: mapSelector(selector: "h3 a") {
      name: attribute(name: "title") {
        value
      }
    }
    price: mapSelector(selector: ".price_color") {
      value: innerText
    }
    stock: mapSelector(selector: ".availability") {
      status: innerText
    }
  }
}
Each entry in data.products comes back with the full book title, a price string such as £51.77, and an availability string such as In stock.
Code node. A Code node reads the scrape from its input and the history with $('Google Sheets').all(), then compares each product's price and stock status with the most recent row for its title.
Filter and action nodes. Unchanged products stop at the filter, while a price drop or a new out-of-stock reading appends a new record to the sheet and posts an alert to Slack, so the team can update inventory or pricing the same day. On the next run, those appended rows become the baseline, so the same change never alerts twice.
Where else price monitoring fits
Any price or stock status that only exists on a rendered page works the same way, from your own e-commerce store to a supplier's catalog. The sheet also doubles as a change history for finance or compliance review.
Use case 5: capture vendor documents and route them for approval
Use case 1 watches a portal for data. Use case 5 keeps a copy of a document, such as a vendor invoice or a utility statement, as the file of record and gets it in front of an approver. Done by hand, someone logs in, downloads it, and forwards it, a step that's easy to forget and hard to audit.
How the document capture workflow runs in n8n
Trigger. A Schedule Trigger checks the portal daily, or a webhook starts the run when a document is due.
HTTP Request node (Browserless /chromium/bql). Browserless signs in with the portal's HTTP credentials, opens the record, and saves it as a PDF for the audit trail, all in a single mutation.
mutation VendorPortalCapture {
  authenticate(username: "user", password: "pass") {
    time
  }
  goto(url: "https://httpbin.org/basic-auth/user/pass") {
    status
  }
  record: mapSelector(selector: "pre") {
    body: innerText
  }
  snapshot: pdf(format: a4, printBackground: true) {
    base64
  }
}
The example authenticates against httpbin's public basic-auth endpoint, so you can run it as written and get the page's JSON ("authenticated": true) in record and the PDF in snapshot.base64. In production, point goto at your portal, and if it uses a login form, replace authenticate with the type and click steps from use case 1.
Code node. A Code node handles the one portal-specific step, parsing the amount and due date with whatever selector or regex fits your layout.
If node. An If node auto-approves anything under your threshold and syncs it to your accounting software. Anything above it goes to a manager in Slack with the PDF attached, once a Convert to File node has turned snapshot.base64 into a file, as in use case 2.
Where else document capture fits
The same document processing works for renewal notices and compliance certificates. Each one reaches the right approver without anyone needing standing access to the portal.
Common mistakes when building custom workflows in n8n
The same handful of problems break workflows in every use case above, and n8n has a built-in fix for each.
- Hardcoded API keys. A token pasted into a node URL is visible to anyone who can open or export the workflow. Store it as an n8n credential, such as Query Auth for the Browserless
tokenparameter, as the Browserless n8n docs recommend. - No error handling. A portal with a slow response time or a changed selector fails the run, and nobody finds out unless you plan for it. Turn on the node's Retry On Fail setting for retry logic, and send failures to an error workflow that writes to an audit log.
- Acting on every run. A workflow that posts the same result every hour trains people to ignore it. Compare against the last stored value and act only on changes, as use case 4 does.
- Default timeouts on slow pages. A
networkIdlewait on a heavy page can outlast the HTTP Request node's default timeout. Raise the timeout in the node's options, and use a lighterwaitUntilor the REST APIs'bestAttemptoption so a page that never fully settles doesn't fail the run. - One giant workflow. A single long flow is a pain to debug. Treat architecture design like code and split it into sub-workflows with the Execute Sub-workflow node, so you can test each piece on its own.
Conclusion
The deciding question for any n8n workflow is whether the data it needs has an API. If it does, built-in nodes and a Code node cover nearly everything, from lead routing to invoice approvals. If it doesn't, the workflow needs a browser that logs in and renders the page the way a visitor would.
Browserless is that browser, called from the same HTTP Request node with a BrowserQL mutation, so your workflows stay in n8n with no Chrome to host. To try it on your own portals and dashboards, sign up for Browserless.
n8n use cases FAQs
When is a simpler automation tool a better fit than n8n?
When a workflow is a single trigger and a single action, with no branching and no need to self-host, simpler hosted automation tools take less setup. n8n pays off once you need branching logic or company data kept on your own infrastructure.
Can n8n be self-hosted?
Yes. Its fair-code license lets you run n8n on your own infrastructure with Docker or Docker Compose, which keeps workflow data inside your network. n8n Cloud is the managed option if you'd rather not run the server yourself.
What are the best n8n use cases for e-commerce?
Price and stock monitoring is the most direct one, as use case 4 shows. Stores also use n8n to sync orders into their accounting software, send a welcome email after a first purchase, and alert a Slack channel when inventory runs low.
Which n8n workflow should you build first?
Start with the process that eats the most hours each week and ties directly to your business objectives. Once that one pays off, it's easier to justify the next.
How should you store API keys in n8n?
In a credential, never in a node's URL or headers. n8n encrypts credentials before saving them to its database, and an exported workflow carries only each credential's name and ID, so the key itself stays on your instance. Watch HTTP Request nodes imported from cURL, which can bring an inline auth header with them.
Can n8n save files to Google Drive?
Yes. Once a Convert to File node has turned a base64 string into a binary file, as in use cases 2 and 5, the Google Drive node's upload operation can store that PDF in any folder your credential can reach.
What is Browserless used for in automation workflows?
Browserless runs headless browsers behind an API, so a workflow can scrape JavaScript-heavy sites, get through login flows, solve CAPTCHAs, or generate screenshots and PDFs from a tool like n8n.
Can an n8n AI agent use a real browser?
Yes, once you connect n8n's MCP Client Tool node to the Browserless MCP server, the agent can browse and read pages on its own. For a fixed step, an HTTP Request node calling BrowserQL is simpler.
Do I need to code to use Browserless with n8n?
No, you can automate most of these workflows with the HTTP Request node and a JSON body, and Browserless publishes copy-paste n8n templates for its main endpoints. A Code node helps when you want to reshape the output.